Your AI visibility report is only worth your prompt set: how to build one that holds up
Almost every AI visibility dashboard measures noise: one run per prompt, brand-name prompts mixed in, generic terms only. The five tiers a prompt set needs, the run protocol around it, and the five columns no tracker logs for you.
Your AI visibility report is only worth your prompt set
The question clients ask is "are we showing up in ChatGPT?". The question worth answering is "with which prompts, in which engine, and how many times out of ten?". Between those two questions sits the prompt set, and most are built badly enough that the dashboard measures its own construction more than the market.
A thread on r/SEO last week was exactly about this: an in-house SEO posted his method for building the prompt list and asked people to poke holes. Six practitioners did, and the corrections converge harder than the original list did. This is that autopsy plus the protocol we run at Mintec, because "we track AI visibility" became a vendor category, and the tooling does not fix a list built from head terms.
The five tiers every set needs
The OP's first rule is the one most teams break: prompts come from buyer questions, not keyword exports. Fifteen to twenty-five prompts, written the way someone asks before they know any brand. The corrections added what the first version was missing: tiers, so the set answers different questions instead of asking the same one fifteen times.
| Tier | Example | What it measures |
|---|---|---|
| Category | "best CRM for dental clinics" | Baseline presence in the category answer |
| Comparison | "X vs Y for a 10-person team" | Where brand names actually surface |
| Alternatives | "alternatives to [competitor]" | Whether you exist outside your own narrative |
| Situation | "CRM for dental clinics with no IT staff" | The slots small brands win first |
| Canary | "[your brand] pricing" | Entity health: if this fails, nothing else matters |
The canary tier deserves its own paragraph. WalkingFoxGR, who runs this for businesses in Greece, keeps two or three brand-name prompts precisely because they fail differently: if the engine cannot describe you when asked by name, that is an entity-data problem, and no category prompt will surface it. Woodoo139 added the trap on the same tier: the engine repeats your question inside the answer, so a brand-name prompt "mentions" you almost every run. That is why they live on a separate line in the sheet, reported apart from category presence.
tRolock5's addition is the situation tier: "best X for small teams in the UK" pulls different brands than the generic version, and it resembles what real buyers actually type. If every prompt in your set is "best X", a small brand sits at zero for months and you cannot tell a badly measured zero from a real one.
The protocol matters as much as the list
Three rules, each learned the hard way by someone in that thread:
- Freeze the wording. Same prompts every run, or you end up measuring your own phrasing changes.
- Fresh, logged-out sessions as the baseline. marintkael: a logged-in account's memory and history pull answers toward whatever that account asked before, which shows what one user sees, not a trend you can report.
- Run each prompt in every engine separately, three to five times each. The same prompt returns different brands in ChatGPT and Gemini; one engine's answer is not "what AI says".
Run count is where single-run dashboards quietly fall apart. WalkingFoxGR asks each prompt three times per engine and reports how often the brand shows up, not whether it showed up. vbgdn, who works on an AI visibility tracker, goes further: with five runs, "3 of 5 against 2 of 5 is noise". He would rather run fewer prompts more times than twenty-five prompts once each.
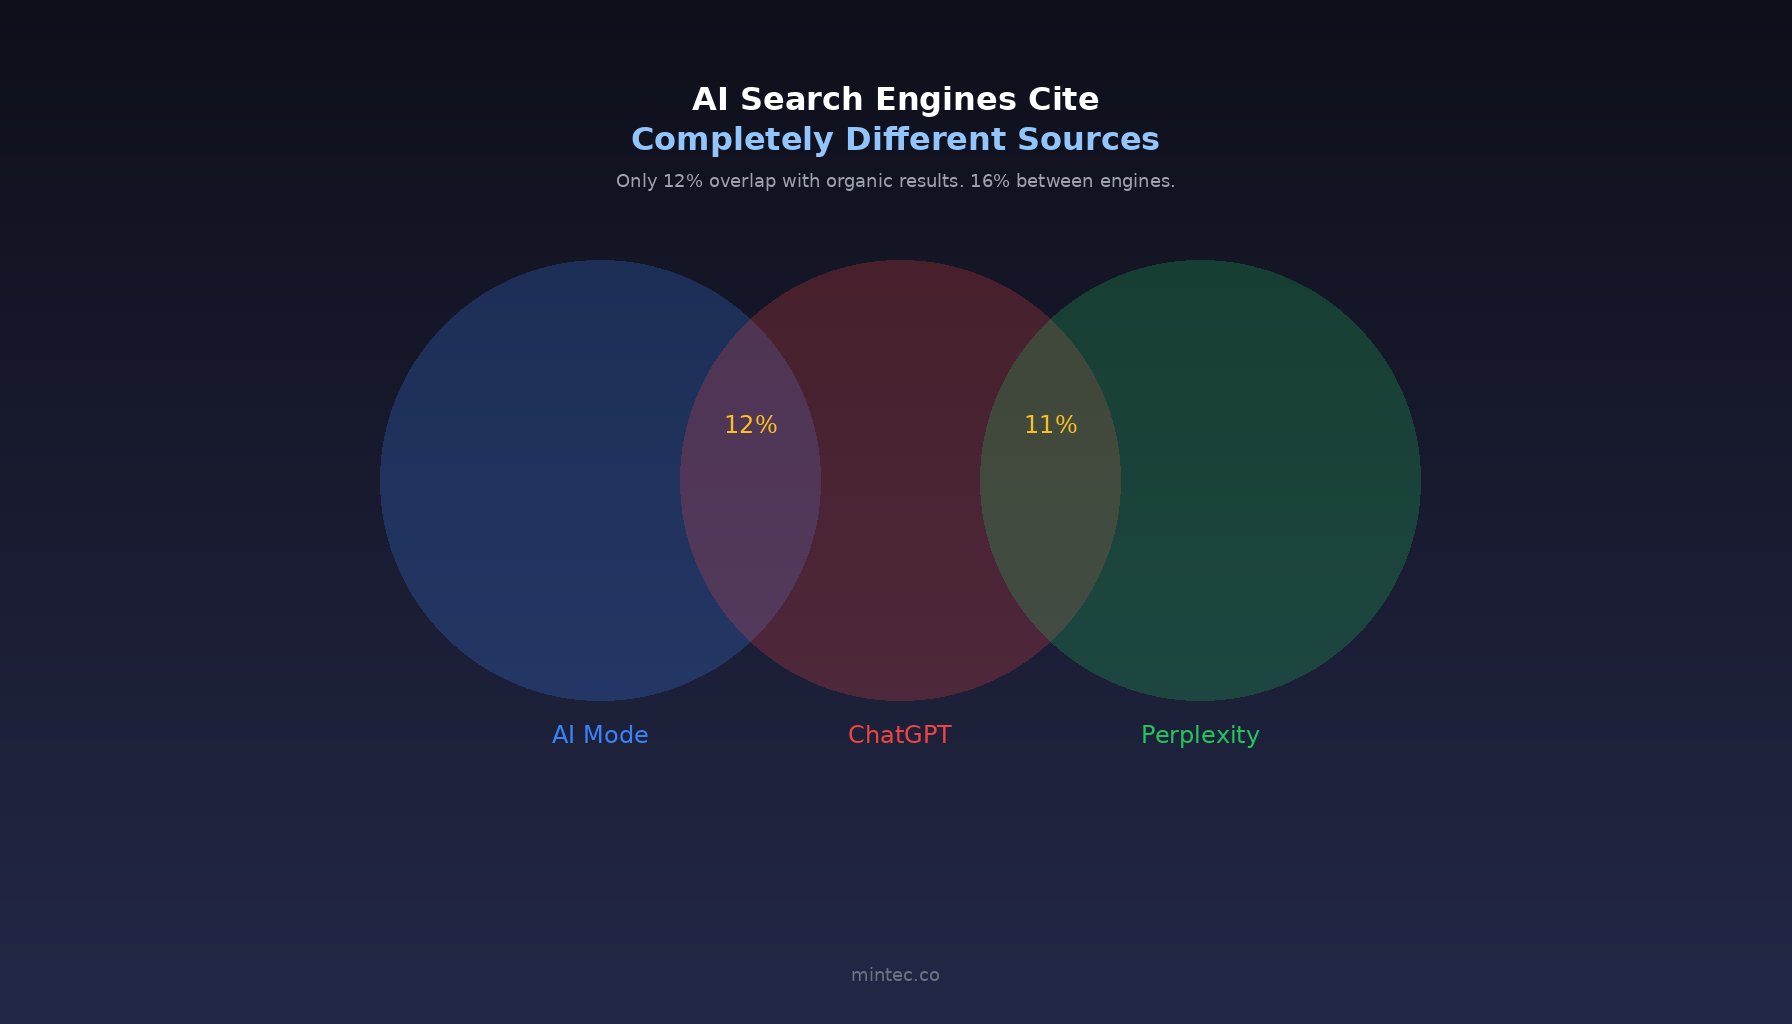
The volatility data backs them up. In SISTRIX's crawl of 82,619 prompts across six countries over 17 weeks, about 47% of cited sources rotated between runs of the same prompt; we broke down what that means for citation order in the first-citation piece. The same logic applies to brand mentions: a single run is a photograph of a coin in the air.
Cadence: every two to four weeks, not daily. Answers vary between runs; daily tracking produces a chart of variance, and clients read charts as trends.
The five columns, not three
Named / position / sources is the OP's baseline. The thread added three columns that ended up deciding what work actually gets done:
- Did the engine search at all? marintkael noticed the same ChatGPT prompt triggers web search on some runs and not others. The sources column only means something on the runs where it did.
- What did it say about you? vbgdn: being named "the expensive option" or "no custom plans" is a different problem from not being named, with a different fix. That is claim fidelity, and we audit it in cited does not mean quoted.
- Timeouts are missing data, not "not named". Woodoo139 learned this the hard way: a bad API day reads as a visibility drop in a naive sheet.
Brand-name prompts get reported on their own line (see canary), and every run logs date, engine, and session state, or the six-week comparison is fiction.
The sources column is where the budget goes
Every practitioner in the thread converged on the same thing: the cited-sources column changed what they worked on more than the mentions column did. WalkingFoxGR found that in his category the independent sources were marketplace and review profiles (Upwork, Clutch), not blogs, so fixing those profiles moved more than another article would have. mazen_SR ran the same audit: adding llms.txt changed nothing in mentions, third-party coverage did; and plenty of cited sources were over two years old, which is worth logging.
There is a real tension here, and vbgdn named it. For "best X" queries, the answer leans on listicles, comparison pages, and Reddit threads. But in his tracker's data, once the buyer's query names brands, brand sites (the brand, its competitors, other sellers) were 64–86% of what got cited per answer depending on the industry, with media and review sites at 5–16%. Both observations fit one picture: third parties decide whether you enter the answer, your own pages decide what the answer says once you are in. That is why GEO work runs on two pipelines, and the acronym map for both sits in the GEO, AEO and SEO framework.
Those 64–86% figures are a practitioner's numbers from a vendor employee in a Reddit thread, not a published study. Useful for orientation, not for quoting in a contract.
Buy the tool or build the spreadsheet
For a first pass: spreadsheet. Fifteen to twenty-five prompts, five tiers, three runs per engine per cycle, adds up to two or three hours a month and answers the client's question with a number that has a denominator. A visibility tool earns its fee when you need history, more engines, large prompt volumes, or someone else noticing the drop. None of that helps if the set underneath is built from head terms. The tool automates the protocol; it does not choose the prompts.
If the site measurement side is not set up yet (Search Console's Generative AI report, GA4's AI Assistant channel), that is the other half, and we walk through it in the measurement stack piece. The prompt set tells you what the engines say; the stack tells you what the visits are worth.
And if the canary with your brand name fails in ChatGPT, the problem may sit upstream of content: how ChatGPT finds your website decides whether you are in its index at all.
What we cannot confirm
The thread's methodology is sound; its numbers are anecdotes with usernames. The 64–86% citation split, the Clutch-over-blogs finding, the "3 of 5 is noise" threshold: all practitioner reports, none published with methodology. What is published and holds: cited sources rotate heavily between runs (SISTRIX, 82,619 prompts), and Search Console's Generative AI report still gives no queries, no citations, and no order, so prompt-level tracking stays manual for now. Better to run a small honest set than a big precise-looking one that measures itself.
Frequently Asked Questions
How many prompts does an AI visibility set need?
Between 15 and 25, split across five tiers: category, comparison, alternatives, situation, and two or three brand canaries. Fewer prompts run three to five times each beat 25 prompts run once, because roughly half the cited sources rotate between runs (SISTRIX, 82,619 prompts).
How many runs before you trust a named / not named result?
Treat 'named' as a rate, not a yes/no. Three to five runs per prompt per engine, in fresh logged-out sessions; report '3 of 5' and the trend across cycles. With five runs, a one-run difference is still noise.
Do I need a paid AI visibility tool to track brand mentions in AI answers?
Not at first. A spreadsheet with 15 to 25 frozen prompts, run every two to four weeks, answers 'are we showing up in ChatGPT' with a number that has a denominator. Tools earn their fee on history, engine coverage, and automated re-runs. They do not fix a set built from head terms alone.