Google says not every page belongs in the index
Google's October 26 spam guide update tells sites to noindex shareable pages, generated outputs and utility tools by default. Here is the audit.
On October 26 Google added a new section to its spam prevention guide: "Only index content meant for Search." The rule is blunt. If your service lets people create shareable pages, generated outputs, or interactive tools, decide whether each page exists to be found or only to be opened by whoever holds the link. Pages built for sharing, collaboration, or utility get noindex by default, applied with a robots meta tag or an X-Robots-Tag header.
That sentence lands differently than it would have two years ago, because the index is no longer only a list of blue links. It is the raw material Google's AI surfaces quote from. A page you leave in the index now competes for the passage an answer engine reads aloud.
What Google actually changed
The update sits in Google's Prevent user-generated spam on your site and platform guide, and Google's changelog dates it October 26. Two additions matter.
The first is the section itself. Its language is unusually direct: pages "created for direct sharing, collaboration, or utility rather than public search discovery" should be noindexed or excluded from crawling by default. The guide used to talk about spammy accounts and comment forms. It now names the architecture: "tools that let users publish shared pages, generated content, or web apps."
The second is the monitoring advice. Google now tells platform owners to track creation and indexing at the platform level and to alert on anomalies, including "a small number of users generating a large share of indexable URLs." That is a sentence written for people who operate systems where users can mint URLs. Search Engine Journal and Search Engine Roundtable covered the change the same day.
This reaches far past spam platforms
It is tempting to file this under advice for SaaS companies with user accounts. Do not. The principle underneath is older than the section: an index slot is supposed to be earned by discovery intent. Any site that generates URLs has pages sitting in the index that were never written for a stranger to find.
Shared links, preview drafts, exported reports, booking confirmations, internal search results, tag pages nobody planned, content from users who joined yesterday: in the audits we run, this layer is invisible to the people who own the site, because nobody wrote those templates and nobody reports on them. They accumulate until the indexed count looks healthy and the traffic chart does not.
Google just wrote the default rule for that layer, and it says no.
The audit: decide per template, not per URL
Reviewing URLs one at a time is the mistake. Decide at the template level, then the whole class moves together.
| Page type | Default | Why |
|---|---|---|
| Share links and shared documents | noindex | The link is the access model. Discovery adds nothing for the sender and exposes content meant for a chosen audience. |
| Generated previews, exports, report pages | noindex | Utility, not discovery. The person who needs it already holds the URL. |
| UGC from new or unproven users | noindex until the account has reputation | Google suggests exactly this in the same guide. Let proven contributors be indexed; do not let day-old accounts mint indexed URLs. |
| Internal search results, tag and filter archives | noindex | The classic index-bloat case, unchanged by any of this. |
| Account, booking and confirmation pages | noindex | A confirmation number is not for strangers. |
| Pages that answer a query your buyers ask | Keep indexed | The rule sorts by intent, not by volume. |
One column is missing on purpose: how many pages each template produces. That number belongs in your own audit, not in a published article.
Getting the list is the boring part, and it is still where teams stall. Export the Page Indexing report, drop the URLs into a spreadsheet, and group them by the path segment that identifies the template: /share/, /preview/, /export/, /search, /u/, whatever your stack uses. Ten minutes of grouping tells you more than an hour of reading individual URLs, because the decision is never really about one page. It is about the rule that produces the next thousand.
The trap that makes the rule fail
Google's section offers two mechanisms: noindex, or blocking crawl in robots.txt. Teams hear "block it" and reach for robots.txt first. That is the wrong order.
If robots.txt prevents Googlebot from fetching a page, Google never reads the noindex on that page. A URL blocked from crawling can still end up in the index as a URL-only entry, with no title, no snippet and no content, and it still counts against you. The directive you actually wanted never got delivered.
So use noindex on a page Google can crawl, wherever the page must stay out of the index. Keep robots.txt for what it is good at: keeping crawlers off paths that should never be fetched at all. The full distinction, including what robots.txt cannot do to an answer engine, is in AI crawlers can fetch you and still not cite you.
What this changes for AI search
Noindex is now a citation decision. AI Overviews and AI Mode run on Google's index. A page that is out of the index cannot be quoted by them, no matter how good the passage is. The switch that used to be housekeeping decides whether an answer engine can see the page at all.
Utility URLs compete with your best pages. Every one you leave indexed eats crawl, gets considered for passage selection, and lands in the report you show your team. Cleaning the index used to be hygiene. It is now part of the argument for why your money pages get quoted.
Third-party engines play by their own rules. ChatGPT and Perplexity fetch under their own policies; noindex governs Google. Do not assume one directive covers all of them, because that is a separate audit.
Index composition is also one of the few variables you control while waiting for Google to change something. That is the same argument we made reading September's rollout, and the reason our triage comes before any content change.
What to do this week
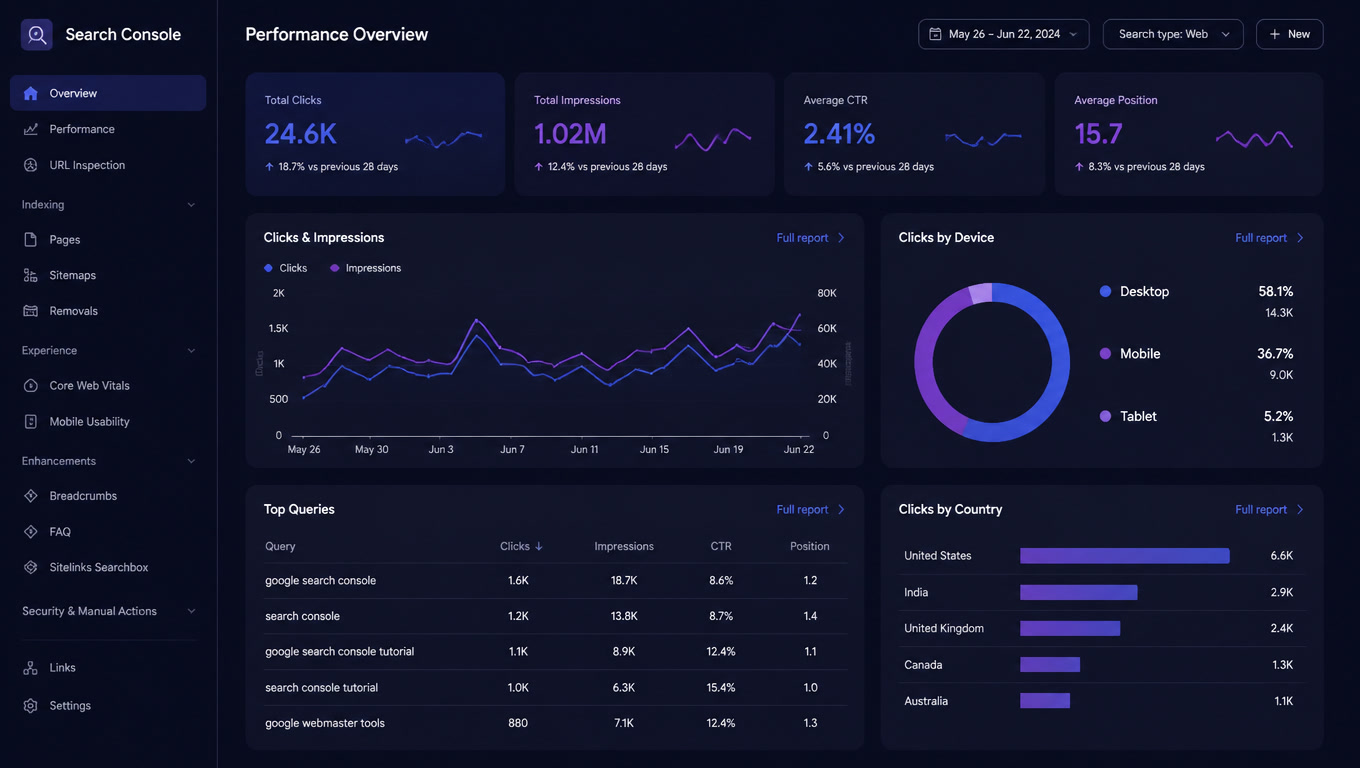
- Open the Page Indexing report in Search Console and group indexed URLs by the template that produced them.
- Assign a default per template: keep,
noindex, or block. Write it down so the next launch does not undo it. - Prefer
noindexover robots.txt wherever the page must stay out of the index, and check that the tag actually reaches Googlebot. - Re-read the report in a week. The indexed count should fall. If a page that earns attention moved with it, you classified wrong: fix the class, not the URL.
- If the audit is the part you never get to, it is the first thing our SEO & GEO team starts with.
Google drew a line between pages built for people who send links and pages built for machines that answer questions. Most sites have never drawn that line themselves. The guide now assumes you will.
Frequently Asked Questions
Should I block crawling or use noindex to keep a page out of Google?
Use noindex on a page Google can crawl, either as a robots meta tag or an X-Robots-Tag HTTP header. If robots.txt prevents Googlebot from fetching the page, Google never reads the noindex, and the URL can still be indexed as a URL-only entry with no title, snippet or content.
Does noindex remove a page from AI Overviews and AI Mode?
Yes, for Google's own AI surfaces. AI Overviews and AI Mode run on Google's index, so a page marked noindex cannot be quoted by them. Third-party answer engines such as ChatGPT and Perplexity fetch under their own policies, so noindex does not govern them.
How do I find pages that should not be indexed?
Start with the Page Indexing report in Search Console and group indexed URLs by template rather than reviewing them one by one. Share links, generated previews, exports, booking confirmations, internal search results and content from new users are the usual suspects, and one decision per template moves the whole class.