Your AI visibility score doesn't predict whether you get cited
Two September 2026 papers measured it: the recommended GEO tactics moved citations on zero of ten engines, and an engine-free score predicts almost nothing.
Two papers published in September 2026 measured what had been an assumption. A content score computed without asking any engine predicts citation order with a Spearman of 0.114. The three tactics everyone recommends for GEO moved citations on none of the ten engines tested. And between two engines answering the same question, mean overlap of cited URLs was 0.0079, with the top five links shared at exactly zero. A number computed without looking at an engine does not tell you whether you get cited, and the tool promising otherwise is selling something its own data does not support.
The two papers
The first is "Scoring Without the Engine" by Elisha Bajemon and Andre-Louis Rochet, posted to arXiv on September 7, 2026. Its stated goal is not GEO, it is validating a cheap proxy for an expensive, rate-limited oracle that changes behavior. GEO is the demonstration domain because it is the only field publishing measurable causal effects.
The second is "Scoring With the Engine" by Benjamin Tannenbaum, September 2026, and it builds on the first: if the earlier paper isolates what happens after an engine exposes a page, this one measures the layer that was missing, what the engine exposes in the first place.
Together they cover the two questions a client always asks, whether the technique works and whether the reporting tool measures anything.
The three tactics move nothing anymore
The GEO playbook comes from the 2023 Princeton paper, which reported these gains in Position-Adjusted Word Count: expert quotations +42.6%, statistics +32.8%, cite-sources +27.7%. We went through Section 6 of that paper, the one almost nobody cites, and the gap between the promoted number and the number measured on Perplexity was already there.
Now there is a harder measurement. Bajemon and Rochet reran the three edits with a control the original study lacked: they appended a content-neutral filler block of the same added length to each edit, separating the effect of the content from the effect of having written more.
The result, across 605 paired records:
| Tactic | Published gain (2023) | Measured effect (n = 605) | gpt-5.x replication (n = 450) |
|---|---|---|---|
| Expert quotations | +42.6% | −0.0009 (p = 0.82) | −0.0106 (p = 0.04 uncorrected) |
| Statistics | +32.8% | −0.0002 (p = 0.96) | −0.0066 (p = 0.25) |
| Cite-sources | +27.7% | −0.0101 (p = 0.04 uncorrected, 0.13 Bonferroni) | −0.0054 (p = 0.34) |
None moved in the published direction. The two intervals that exclude zero are negative. On the larger pooled set, in percentage points: quotations −0.33 (95% CI −0.84 to +0.17, n = 1,531), statistics −0.28 (−0.97 to +0.43, n = 1,087), cite-sources −0.79 (−1.53 to −0.14, n = 1,087). The published figures were +42.6, +32.8 and +27.7.
The engines: six open-weights families (mistral-medium-3.5, gemma-4-31b, nex-n2-pro, gpt-oss-120b, qwen3.5-122b, llama-3.3-70b), gemini-3.1-flash-lite, and a July 2026 replication on gpt-5.5, gpt-5.4 and gpt-5.4-mini with 150 queries each. In total, ten engine families and 229 unique queries.
There is a detail that should make anyone who has presented a 30-day GEO test uncomfortable. An interim arm with 41 queries showed a positive quotation effect of +0.027. At 100 queries it had washed out to +0.005. Small GEO tests do not fail out of bad faith, they fail on power.
The authors bound their own conclusion, and it is worth quoting: the test regime is a controlled proxy (five curated sources, a fixed citation format, a PAWC-like share), so part of the non-transfer could be an artifact of the frame rather than of the engines. They are not saying the techniques never worked. They are saying you can no longer claim they work today.
The number that survived its own refutation
We went looking for where the +33% statistics figure was still circulating and landed on a page updated in September 2026 titled "How to Use Statistics to Boost AI Citations by 33% (2026 Data)". Its own update box reports the replication result: −0.276 percentage points, interval −0.970 to 0.425, n = 1,087. The headline advertises the gain, the paragraph underneath says the gain did not appear.
That is not a stray error, it is the whole mechanism by which a number becomes canonical. Someone publishes a result, the result becomes a slide, the slide outlives the paper that killed it, and three years later the number cites with authority a study that measured it at zero. If your agency is still presenting "+33% visibility from statistics", ask which sample, against what control, over how many queries.
One engine is not the others
Tannenbaum ran the audit that was missing. On June 6, 2026 he ran the same 15 commercial prompts against ChatGPT, Microsoft Copilot, Google and Perplexity and recorded 589 citation observations: 528 unique URLs, 356 domains.
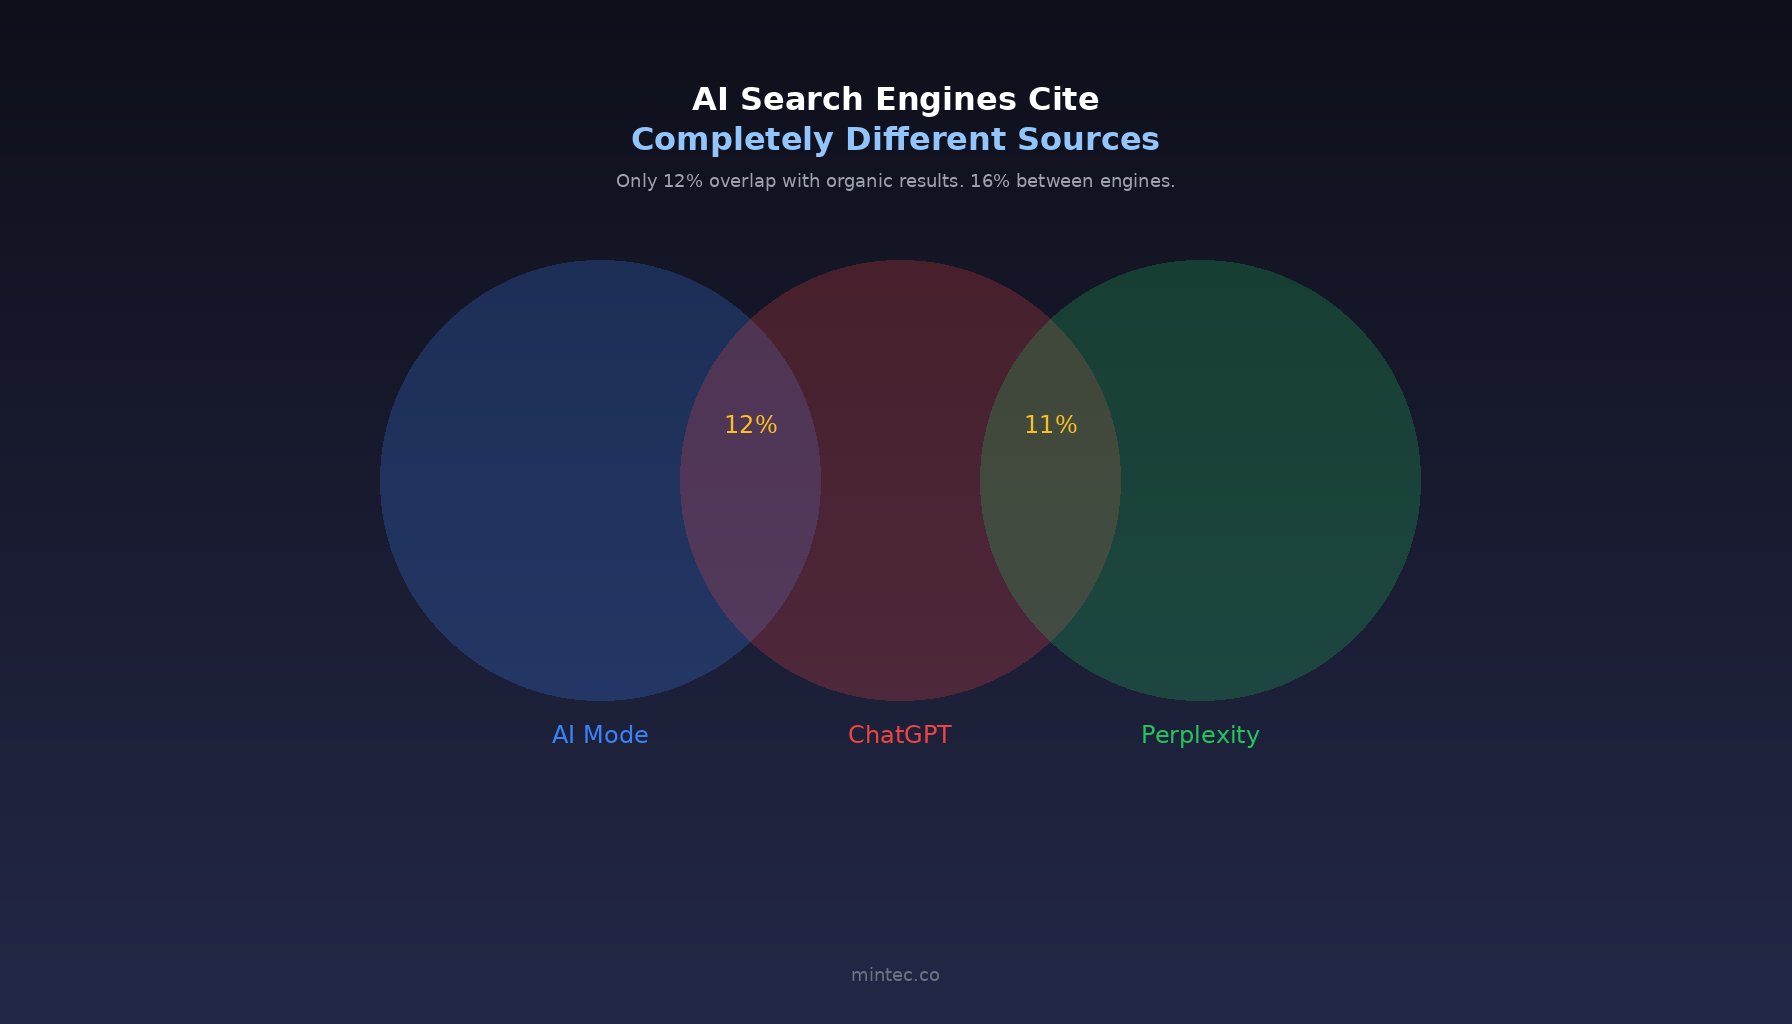
- Mean exact-URL overlap between two engines for the same prompt: 0.0079 (95% CI 0.0037 to 0.0132). The median is zero. 84.9% of engine pairs shared no URL at all.
- On the ten prompts all four engines answered, top-five overlap was exactly zero across all 60 comparisons. There is no shared core at the top of the list: no pair of engines shared a URL within their first five citation positions.
- A single engine captured between 11.4% and 42.6% of the four-engine union (ChatGPT 42.6%, Google 24.3%, Perplexity 23.6%, Copilot 11.4%). None reaches half.
- 96.4% of observed URLs appeared on exactly one engine.
- The next day, the same engine had already changed 67.0% of its URLs (95% CI 61.1% to 72.2%). Even so, one engine compared with itself the next day was about 42 times more similar than two engines on the same day.
Measure one engine and treat it as "AI search" and you miss most of the sources that appear elsewhere. Single-engine reporting still works, as long as you say which engine you measured and on what date.
What an engine-free score can and cannot do
Back to the 0.114. It is the within-query Spearman between the paper's score and citation order across 777 groups, at p = 1.5 × 10⁻⁹, replicated at 0.118 on the three gpt-5.x arms. It is real signal and statistically solid. It is also small: a score that only reads the page text explains a tiny fraction of who gets cited.
The paper goes further and tests whether a more flexible model improves on it. A LambdaMART ranker restricted to content features reaches 0.10 against 0.12 for the fixed score, so it does not win on unseen queries. When the model receives the query, the signal roughly triples to around 0.4. And a regex-only ranker, whose entire job is comparing query lexically against source, reaches 0.222. So what matters most is not how well your page is written. It is how well it matches the specific question that person asked.
The score does have a property no ranking tool has demonstrated: it is hard to game. Amplifying any of its calibrated levers gains at most 6 points, the gain decreases with dose, and it does not stack across levers. As a content quality gate it earns its keep. As a citation forecast it does not.
The four-quantity framework
Tannenbaum proposes stopping the practice of reporting all of this as one number. It is the frame we adopted:
| Quantity | What it measures | Who can measure it | What it cannot claim |
|---|---|---|---|
| Page fit | Quality and match of the text against a query | Engine-free score, editorial audit | That the engine will expose it |
| Exposure | Whether the engine searched, retrieved and put the page in context | Internal engine logs, which nobody outside has | That exposure becomes citation |
| Conditional selection | Of the exposed pages, which get cited | Fixed candidate-set experiments | End-to-end visibility |
| Final visibility | What the engine cited for that query | Dated, fixed-prompt audit on more than one engine | Anything without declaring engine and date |
The rule that follows: an AI visibility number with no declared engine and no date is not a probability of being cited, it is a page score with an ambitious name.
What we report today
None of this leads us to stop measuring, it leads us to separate the quantities. The protocol we run:
- If we use a score at all, it goes in as a quality gate on the content pipeline, not as a citation forecast. It is good at catching pages with low data density or unreadable structure, which is what it does well.
- Citations are read with a fixed, dated prompt panel across at least two engines. We already wrote that a screenshot of one answer is a sample, not a result, and with 67% daily turnover that rule weighs more than it did a month ago.
- In Search Console we report generative AI report pages alongside position as a range with a caveat, not as a rank, because Google still counts the whole block as a single result.
- Indicators that survive a definition change get tracked separately: pages cited, brand search, direct traffic.
- Before we buy or renew a tool, we ask the agency to show exactly what it measures and against what. If the answer is a number with no engine and no date, it is not a measurement.
What to do this week
Take the latest AI visibility report you have, any of it, and write three things next to each figure: which engine, which query, which date. If you cannot supply all three, the figure cannot be defended in front of a client.
Then review the content you are "optimizing for GEO" right now. If the plan is to add a statistic every 200 words to gain 33%, that figure has been measured on ten engines and it came out at zero. Put the effort where the signal actually moves: make the page answer the specific query you expect to be found for, and put that answer in the opening paragraphs.
AI visibility measurement will stay approximate for a long time, and an approximate number holds up in front of a client as long as it carries an engine and a date. Billing a page score as a citation forecast does not.
Frequently Asked Questions
How well does a content score predict AI citations?
In Bajemon and Rochet's September 2026 study, a score computed from page text alone reached a within-query Spearman of 0.114 across 777 groups, and 0.118 when replicated out of family on three gpt-5.x engines. The signal is real but small: it works as a quality filter, not as a citation forecast.
Do statistics and source citations still win AI citations?
Not that has been shown on current engines. The three strongest tactics from the Princeton paper (expert quotations, statistics, cite-sources) moved citations on none of ten engines under paired, volume-controlled edits. What does move the signal is query relevance, which roughly triples the page score when the model receives it.
Can I treat one engine as a sample of AI search?
Yes, as long as you call it a sample. In a four-engine audit of the same 15 prompts, mean URL overlap between two engines was 0.0079 and top-five overlap was zero in all 60 comparisons. 96.4% of cited URLs appeared on exactly one engine, so a single-engine reading misses most of what the others say.